Grok 4.7
Grok 4.7 vs Muse Spark 1.3
SpaceXAI dropped Grok 4.7 today, 19 days after Meta AI released Muse Spark 1.3.
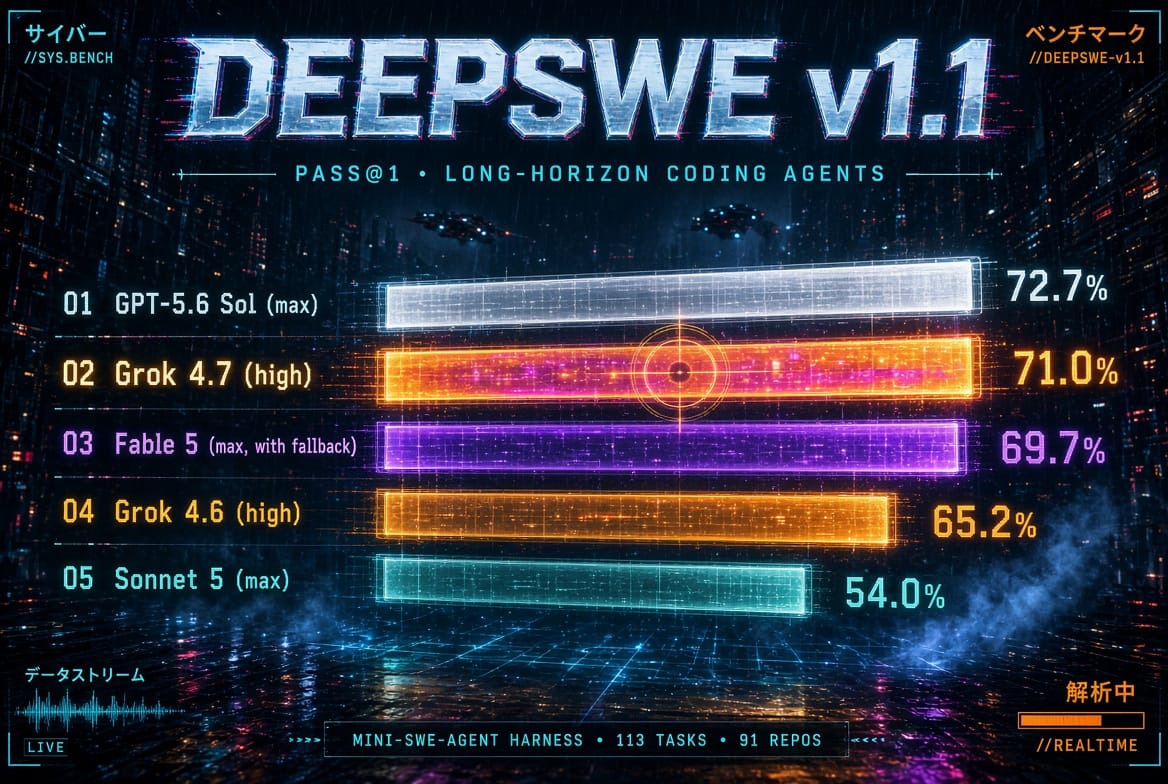
Grok 4.7 is the same price and speed as Grok 4.6 — and a real step up where it counts. Built on a larger base and trained longer on multi-hour coding and knowledge-work problems, it stays on hard tasks, checks its own work more carefully, and handles long context better.
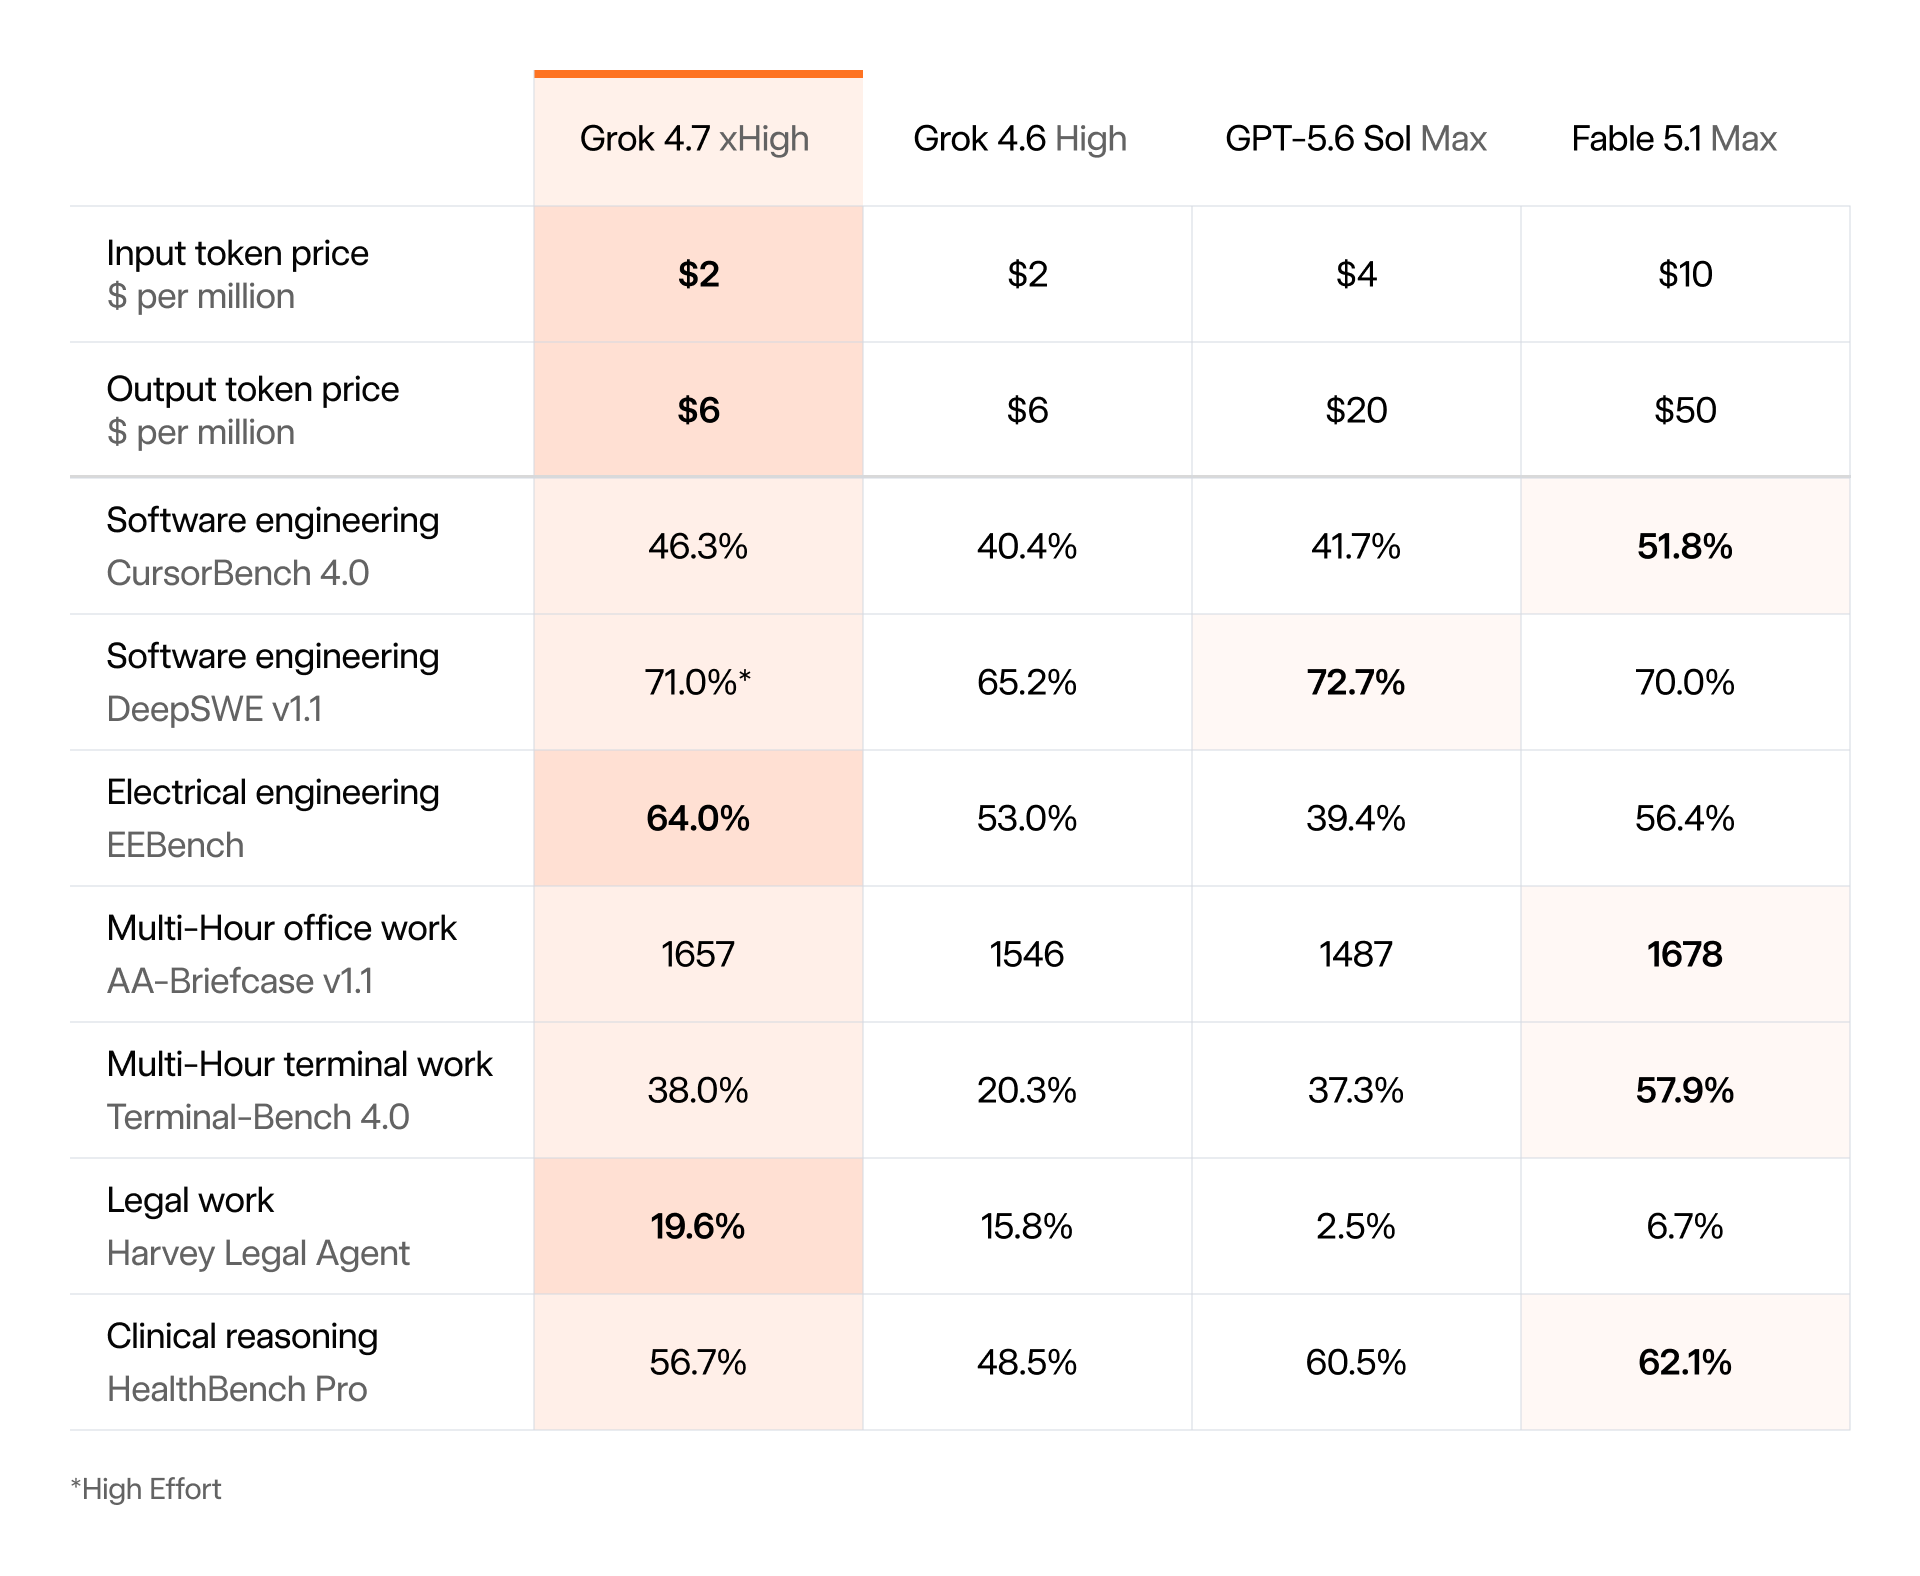
On CursorBench 4.0 it jumps from 40.4% to 46.3%. On Terminal-Bench 4.0 it nearly doubles, 20.3% to 38.0%. Gains also show up in electrical engineering, legal agent work, office tasks, and documents. Same $2 / $6 per million tokens. Stronger safeguards, same blunt Grok voice.
If 4.6 was already the value play for agents and code, 4.7 is the version you actually want to leave running.
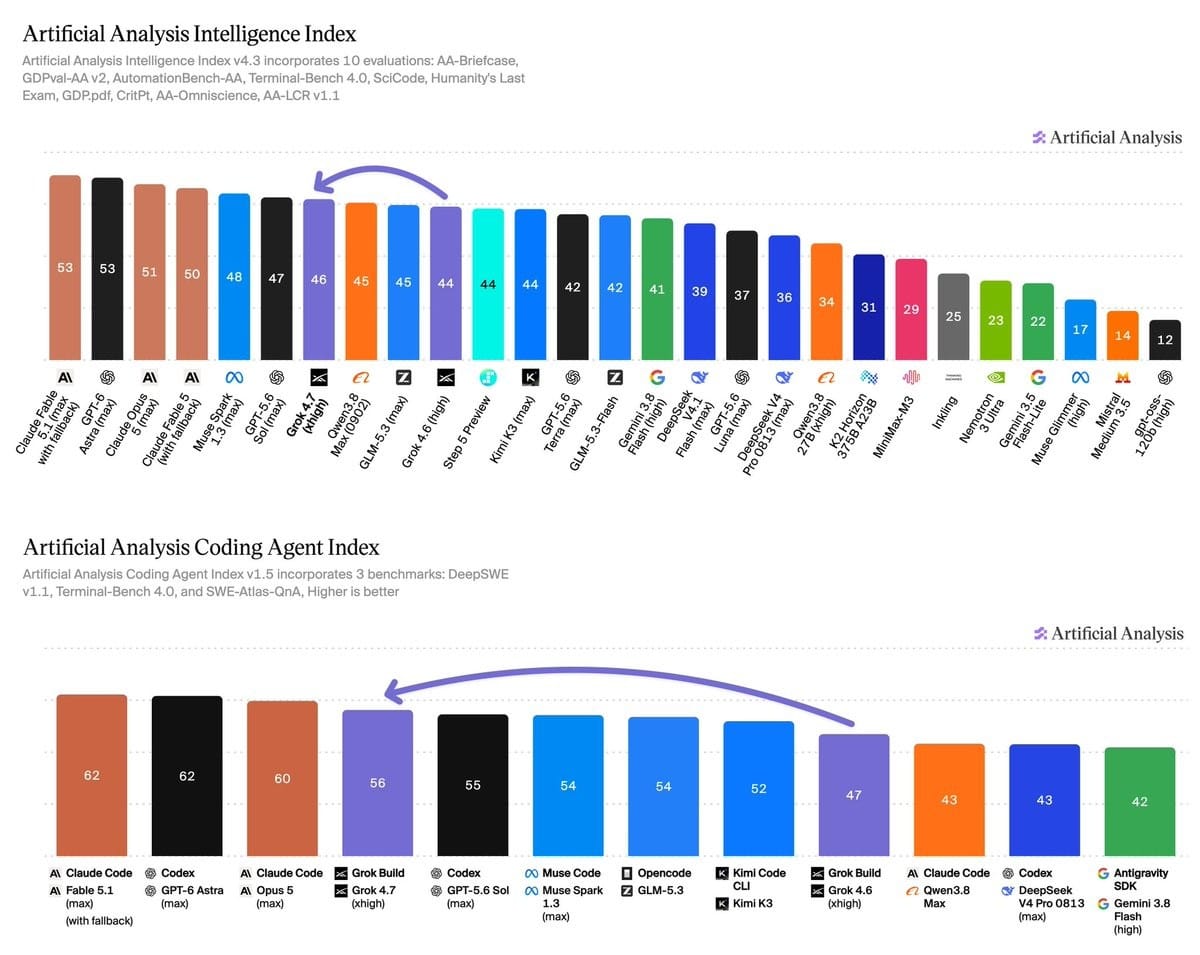
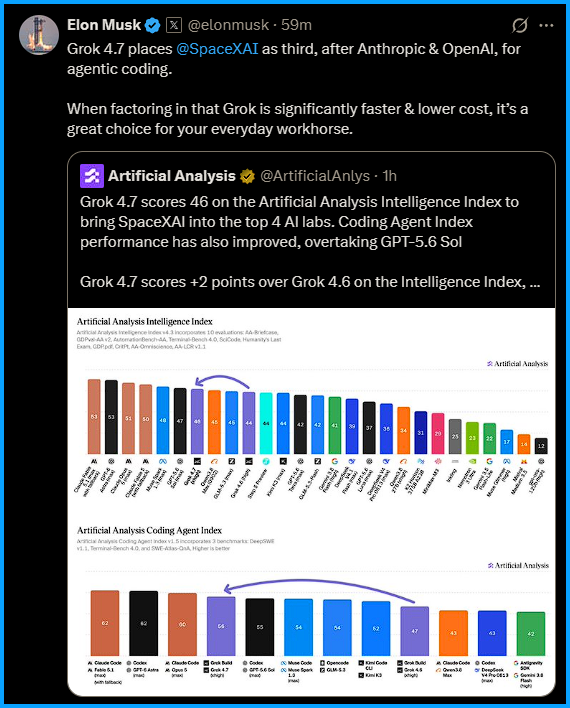
Early benchmarks from Artificial Analysis show Grok slightly behind Muse Spark on the Intelligence Index at 46, 2 points behind. However on their Coding Agent Index Grok is 2 points higher at 56. Which Musk points out is 3rd place overall.
Grok 4.7 takes 1st place in the Electrical Engineering EEBench and Legal Work, Harvey Legal Agent. It's also much cheaper than GPT and Fable.
My preferred harness for Grok is Hermes Agent from Nous Research. https://karmanprime.com/hermes-agent/
On the x.ai website you can view and download the Grok 4.7 Model card. It goes into a lot more detail on different benchmarks. A couple of the big jumps from Grok 4.6 were on Terminal-Bench: 20.3% → 38.0% and SWE-Marathon: 31.9% → 46.0%.
https://media.x.ai/v1/website/4p7card-5eccc980.pdf